Product Page Optimization and store listing experiments without guesswork
A store test is useful only when it examines a specific uncertainty. Variants without a hypothesis generate numbers but rarely produce a dependable product decision.
Apple Product Page Optimization and Google Play store listing experiments give product teams native test capabilities. Their setup and reporting differ, but the production rule is the same: define the question and audience first, then change the variable that answers it.
Every test needs a baseline. We document the current assets, market, period, traffic source and the decision that will follow from a result. Without this context, later differences are difficult to interpret.
Write a testable hypothesis
‘The new image is better’ is not a hypothesis. A useful version is: ‘If the first asset shows the completed workflow instead of the start screen, new visitors will understand the core value more quickly.’ The change, audience and expected effect are explicit.
The hypothesis should come from user feedback, store data or an observable comprehension gap. Testing is not a substitute for knowing the product.
Change one meaningful variable
If the icon, screenshot order and copy all change together, the outcome cannot be assigned cleanly. Early tests should isolate one clear visual or verbal lever.
Variants still need equal production quality. An obviously weak control against a complete redesign is not a fair comparison.
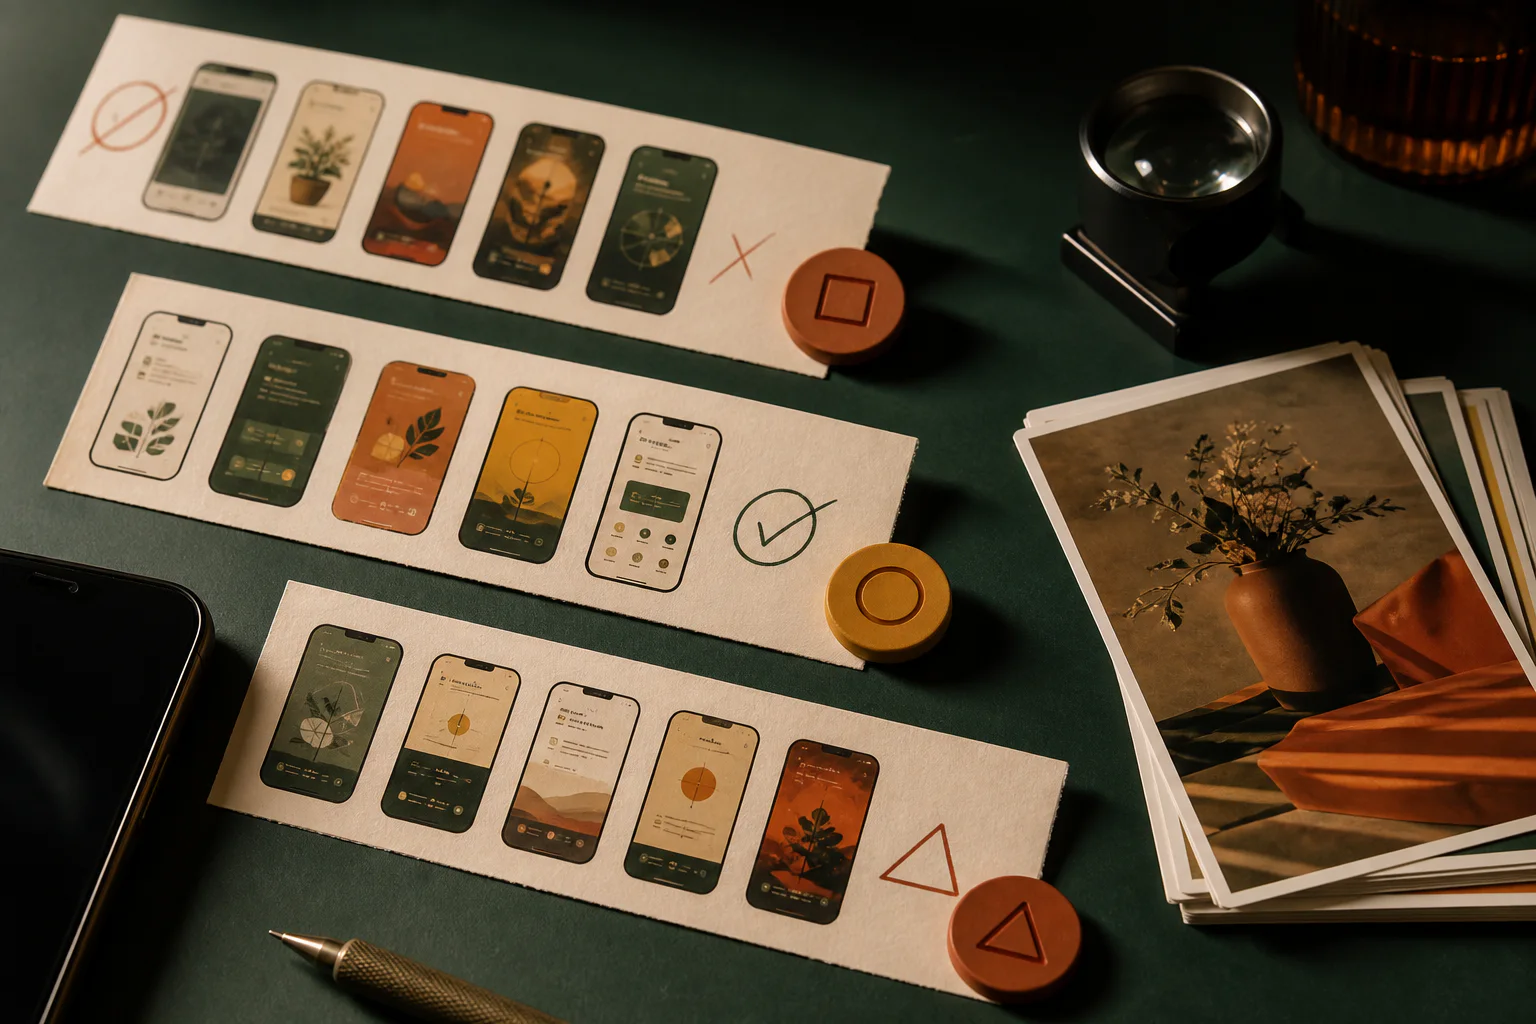
‘The new image is better’ is not a hypothesis. A useful version is: ‘If the first asset shows the completed workflow instead of the start screen, new visitors will understand the core value more quickly.’ The change, audience and expected effect are explicit.
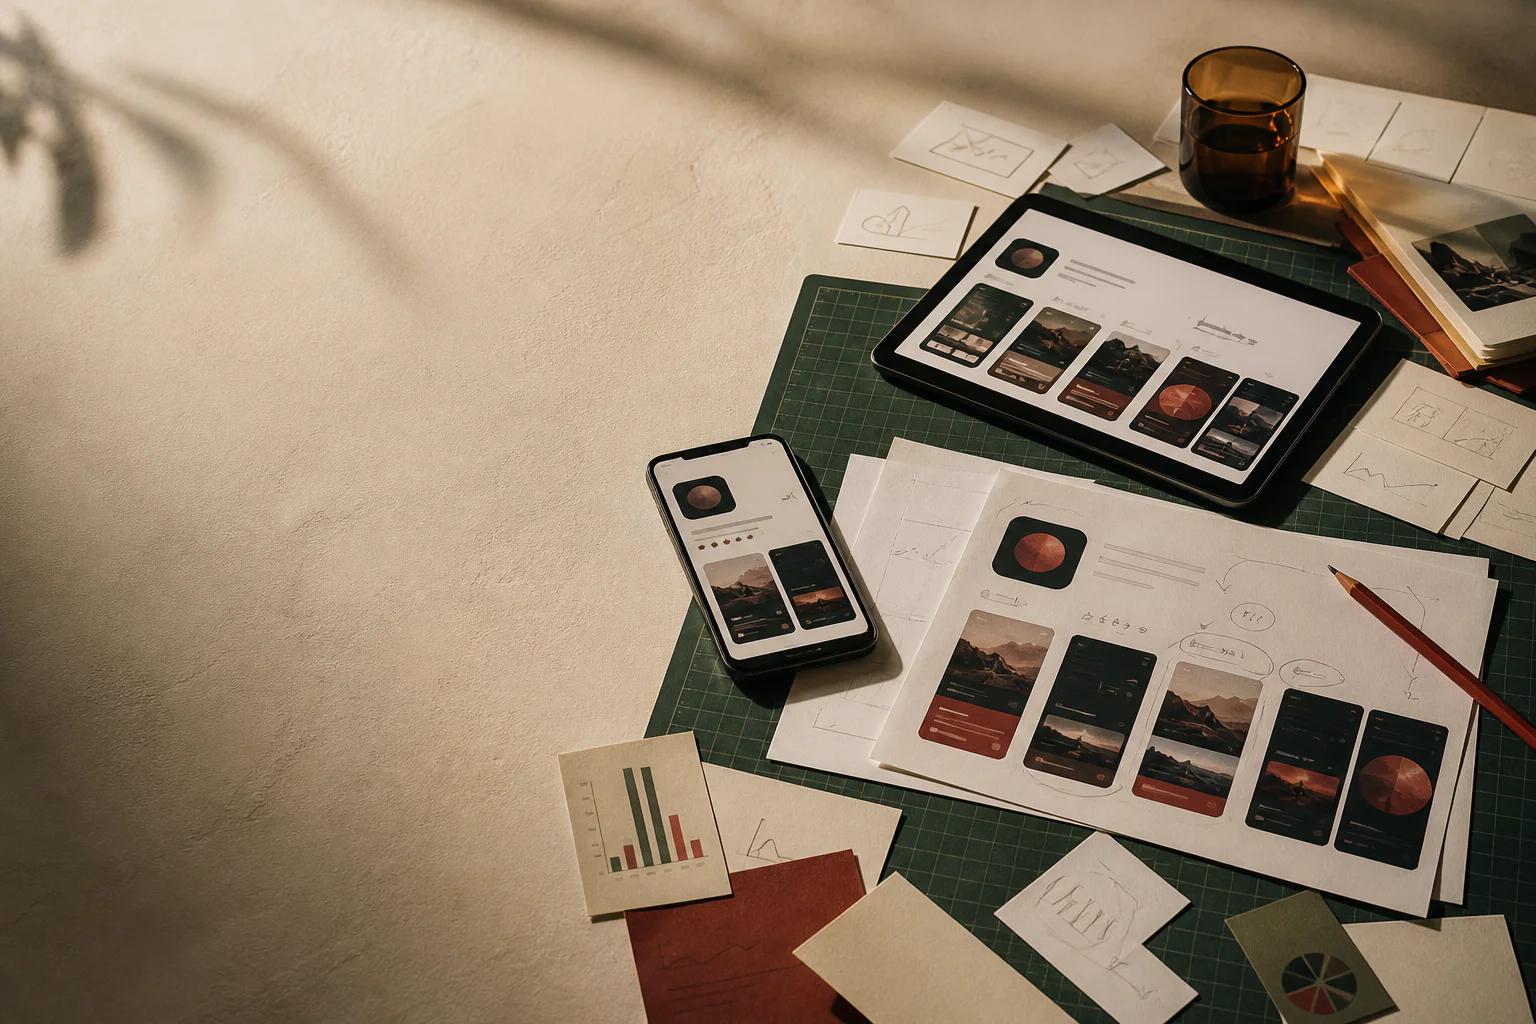
If the icon, screenshot order and copy all change together, the outcome cannot be assigned cleanly. Early tests should isolate one clear visual or verbal lever.
Read platform results carefully
Google Play notes that an experiment may need more data or end in a draw. Apple reports confidence and may classify treatments as better, worse or likely inconclusive. No winner is a valid result.
We record context, duration and possible confounders alongside the chosen asset. Seasonality, campaigns and product releases can shift the comparison.
Feed the result back into the product
A store test can show which presentation is clearer. It does not automatically prove that the product has improved. Install steps, activation, usage and support questions remain separate signals.
A credible cycle ends with one of three decisions: apply a treatment, keep the baseline, or test a more precise hypothesis.
A seven-line experiment brief
A clear start does not need more.
- Target market and store
- Affected audience
- Observed problem
- One hypothesis
- One meaningful change
- Decision rule defined in advance
- Documented baseline
Fewer random variants, better questions
We build a prioritized experiment backlog, produce the assets and keep the decision traceable. That reduces activity without learning and protects the team from false certainty.
View the related serviceReviewed primary sources
Platform rules change. Each guide therefore links to the official material behind its technical statements.